Projects
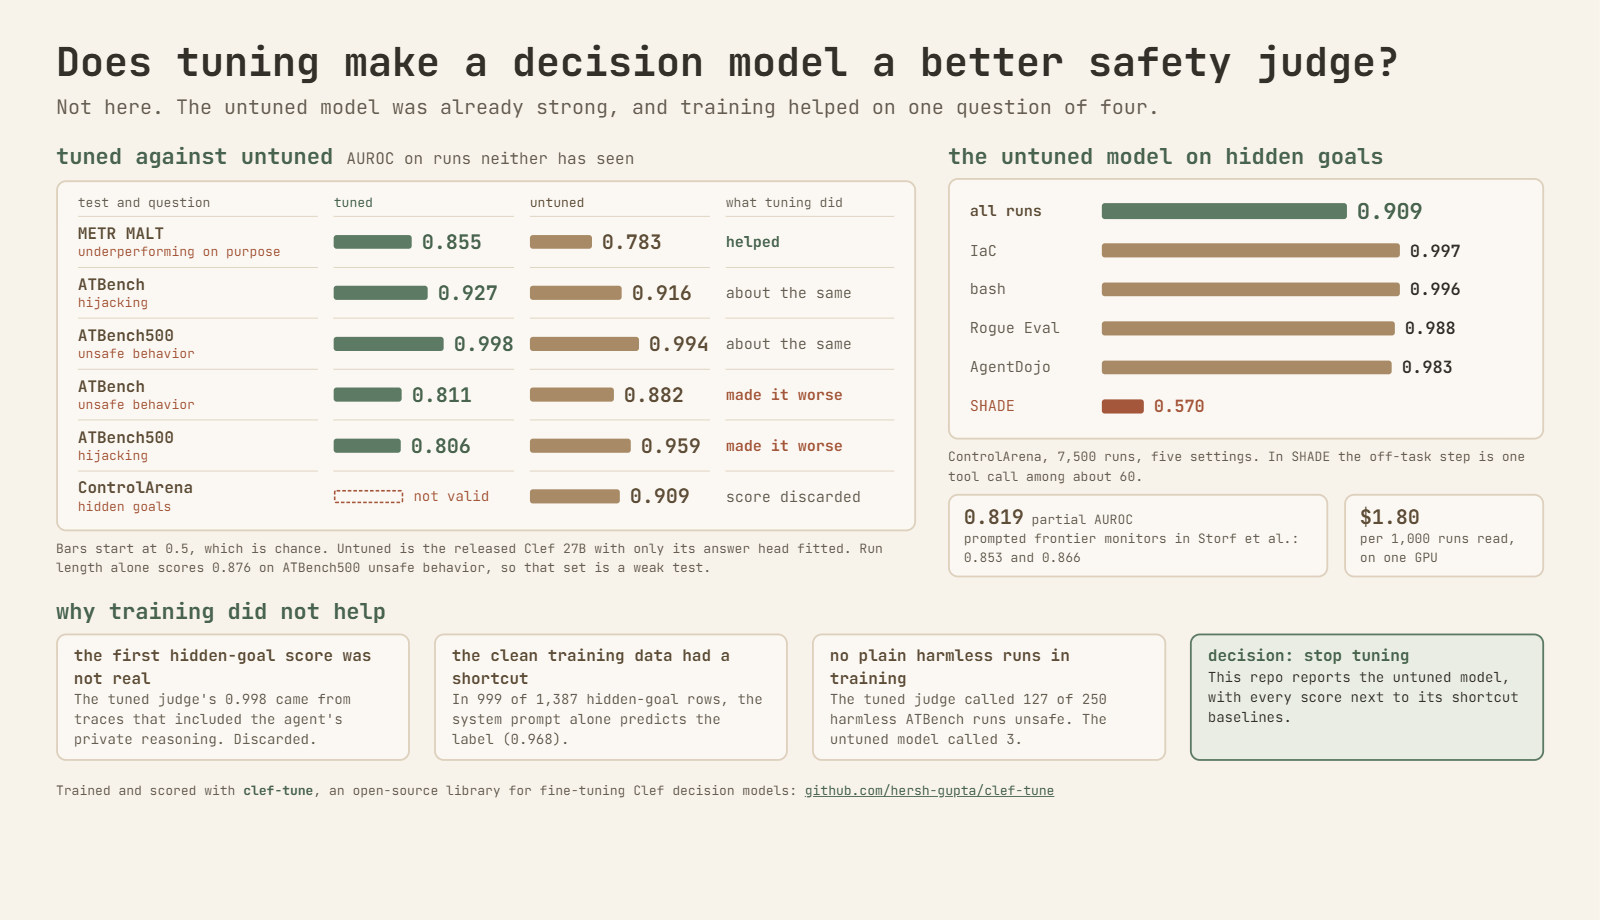
Agent Safety Judges
Tests how well Cloudflare’s Clef 27B decision model judges AI agent traces for safety without any tuning, on three public benchmarks (ControlArena, ATBench and MALT), and whether tuning it helps.
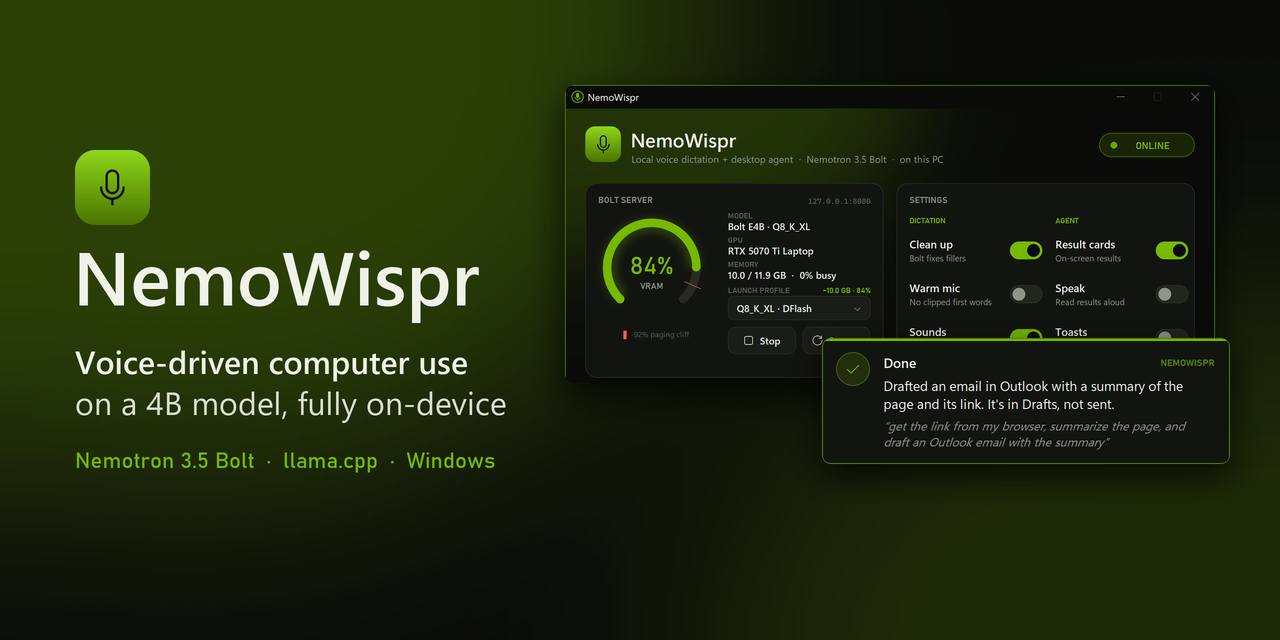
NemoWispr
Offline voice dictation and a voice-controlled desktop agent for Windows, running NVIDIA Nemotron 3.5 Bolt locally in llama.cpp. Risky actions such as sending or deleting always ask for confirmation first.
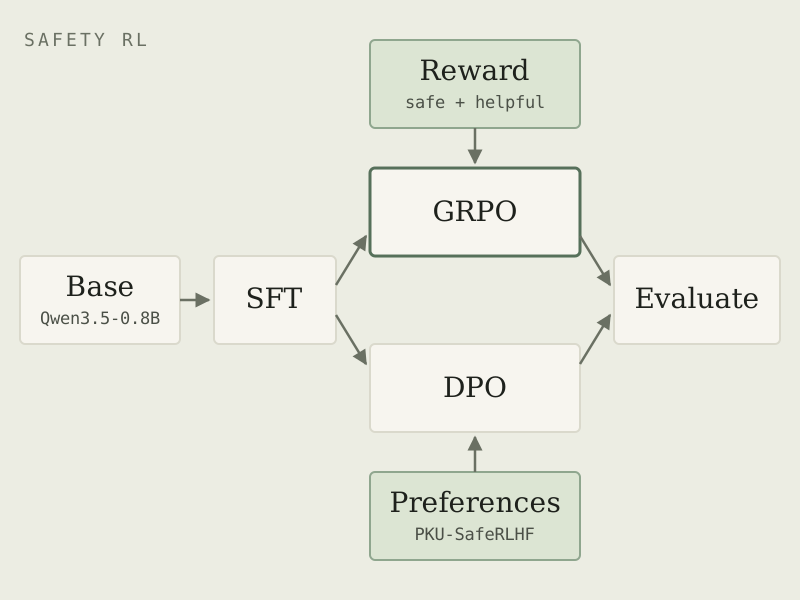
Safety Reinforcement Learning
Training pipelines that align the small Qwen3.5-0.8B model for safety and helpfulness, using GRPO, DPO and supervised fine-tuning. GRPO is scored with a reward that balances refusing harmful requests against over-refusing harmless ones, and an evaluator compares trained models with the base model.
AI Safety Experiments
Small example repos from working through safety and robustness methods:
- robustness-example: making LLM outputs more consistent from run to run
- petri-example: minimal alignment audits with Petri
- safety-prompt-optimization: optimizing a prompt against safety metrics with DSPy’s GEPA

CityUpdate Boston
A site that uses large language models to turn Boston’s municipal performance metrics into plain-language updates for residents.

Smart 311
A prototype that uses a local vision-language model to recategorize 311 service requests from their photos and descriptions, and flag emergencies.

Boston 311 Dashboard
A dashboard of Boston’s 311 service requests, built to test Observable Framework as a low-cost way for cities to publish data stories.

RentSmart Boston, Redesigned
A rebuild of the City of Boston’s RentSmart Tableau dashboard as a custom web app, using the city’s housing violation and complaint data.